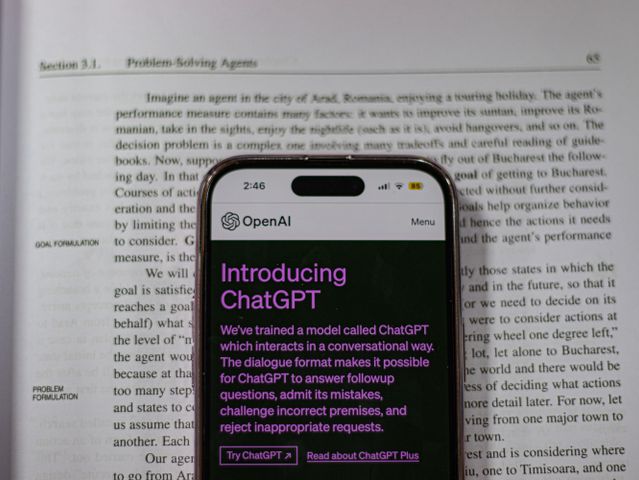
LOS ANGELES, September 8, 2026 – It was one of those Tuesday mornings which are usually not very eventful. However, on this particular morning, developers, researchers, and enthusiasts opened their emails to find out that a much-hyped artificial intelligence system had finally been released. There has been no weeks-long build-up; everything came suddenly and quietly and instantly raised the bar of what can be achieved with machines.
According to detailed coverage of the news, GPT-6 Astra is being officially introduced to the world. Based on a new architecture, the system is a revolutionary improvement in multimodal reasoning, the capabilities of autonomous agents, and context management. Frankly speaking, this is quite perfect timing.
While some of the early benchmarks are still being released, it seems that GPT-6 is much better at performing multi-step logic than its predecessors. The system does not just generate code or summarize lengthy papers but plans actions, checks the logic itself, and executes workflows with multiple tiers. “Astra represents a fundamental step forward in computer-use capabilities, allowing systems to independently execute multi-step digital workflows,” said an AI safety researcher following the launch.
Here’s the catch: While the technological accomplishments can’t be denied, the quick adoption is creating ripples in the larger tech community. Observers in the industry are frantically trying to understand the implications for enterprise integration, software engineering, and the quest for AGI.
Based on the latest news, the rollout is being done gradually. Access to the tiered APIs ($10 per million input tokens) is currently rolling out to enterprise partners, and wider access will be available in the coming weeks. This hasn’t deterred developers from staying up until 3:00 AM to try out its limits and push the 1- million-token context window to its extreme ends.
Does it still stumble? Yes. The hallucinations have not disappeared – no one really thought they would – but early red-teaming indicates that the number of such mistakes has considerably reduced.
It is not just the raw benchmarking scores that make Astra so interesting, but rather the efficiency at which they are achieved. According to insiders working on the project, the compute overhead needed for the execution of Astra’s primary inference is unexpectedly efficient compared to its parameter count. This is critical because the entire world of data centers is increasingly facing problems with energy shortages and high costs of running their operations.
The discussions on the limits of current scaling laws had been going on for months until Astra broke the myth. It shows that it is possible to achieve exponential gains from the combination of algorithmic improvements and large-scale data collection.
With the deployment underway in different regions, companies and developers have a pressing question on their minds once again: how soon can they adopt the changes? The answer to this is always the same – yesterday.